I train models on structured physical data, then take them apart to
see what they actually learned.
Four years in experimental high-energy physics taught me that a
number without an error bar is a rumor. I bring that to machine
learning: build the model, then run the ablation that tells you
why it works. Currently at the LA Public Library on the
operations side, and looking for research engineer and applied
scientist roles.
Work
Capacity and data unlock each other
Transformer · Lichess GM games · UCI tokenization, closed-form
1,973-token vocabulary · 2×2 ablation over corpus size and model
capacity
A GPT-style model trained to predict the next move in a game. The
interesting question wasn't strength, it was legality: what has to
be true inside a model before it stops proposing moves that don't
exist on the board?
Four checkpoints across two corpus sizes and two architectures.
Scaling data alone takes fully-legal games from 4.4% to 11.4%.
Scaling capacity alone takes it to 9.8%. Both together take it to
51.8%, roughly 12× baseline and four to five times what either
intervention reaches on its own. They don't contribute separable
gains; each one unlocks the other.
Linear probes suggest what the extra depth buys. Measured against
the same probe trained on a random-initialized model of identical
architecture, which already scores well above chance on board
statistics alone, the 12-layer model closes 84.6% of the remaining
gap, peaking at layer 9 of 12. The 6-layer model is still climbing
at its final layer and never gets there.
Fig. 1 Fully-legal games out of 500
per condition, model playing White. Neither intervention is the
bottleneck alone.
Legality isn't strength. Against Stockfish, the only statistically
significant win-rate gap across the whole skill range is at skill
0. And one row cuts against the story: the 12-layer model on the
small corpus has by far the worst validation loss in the table,
yet better legality than the 6-layer model trained on the same
data. Why isn't something this project measured.
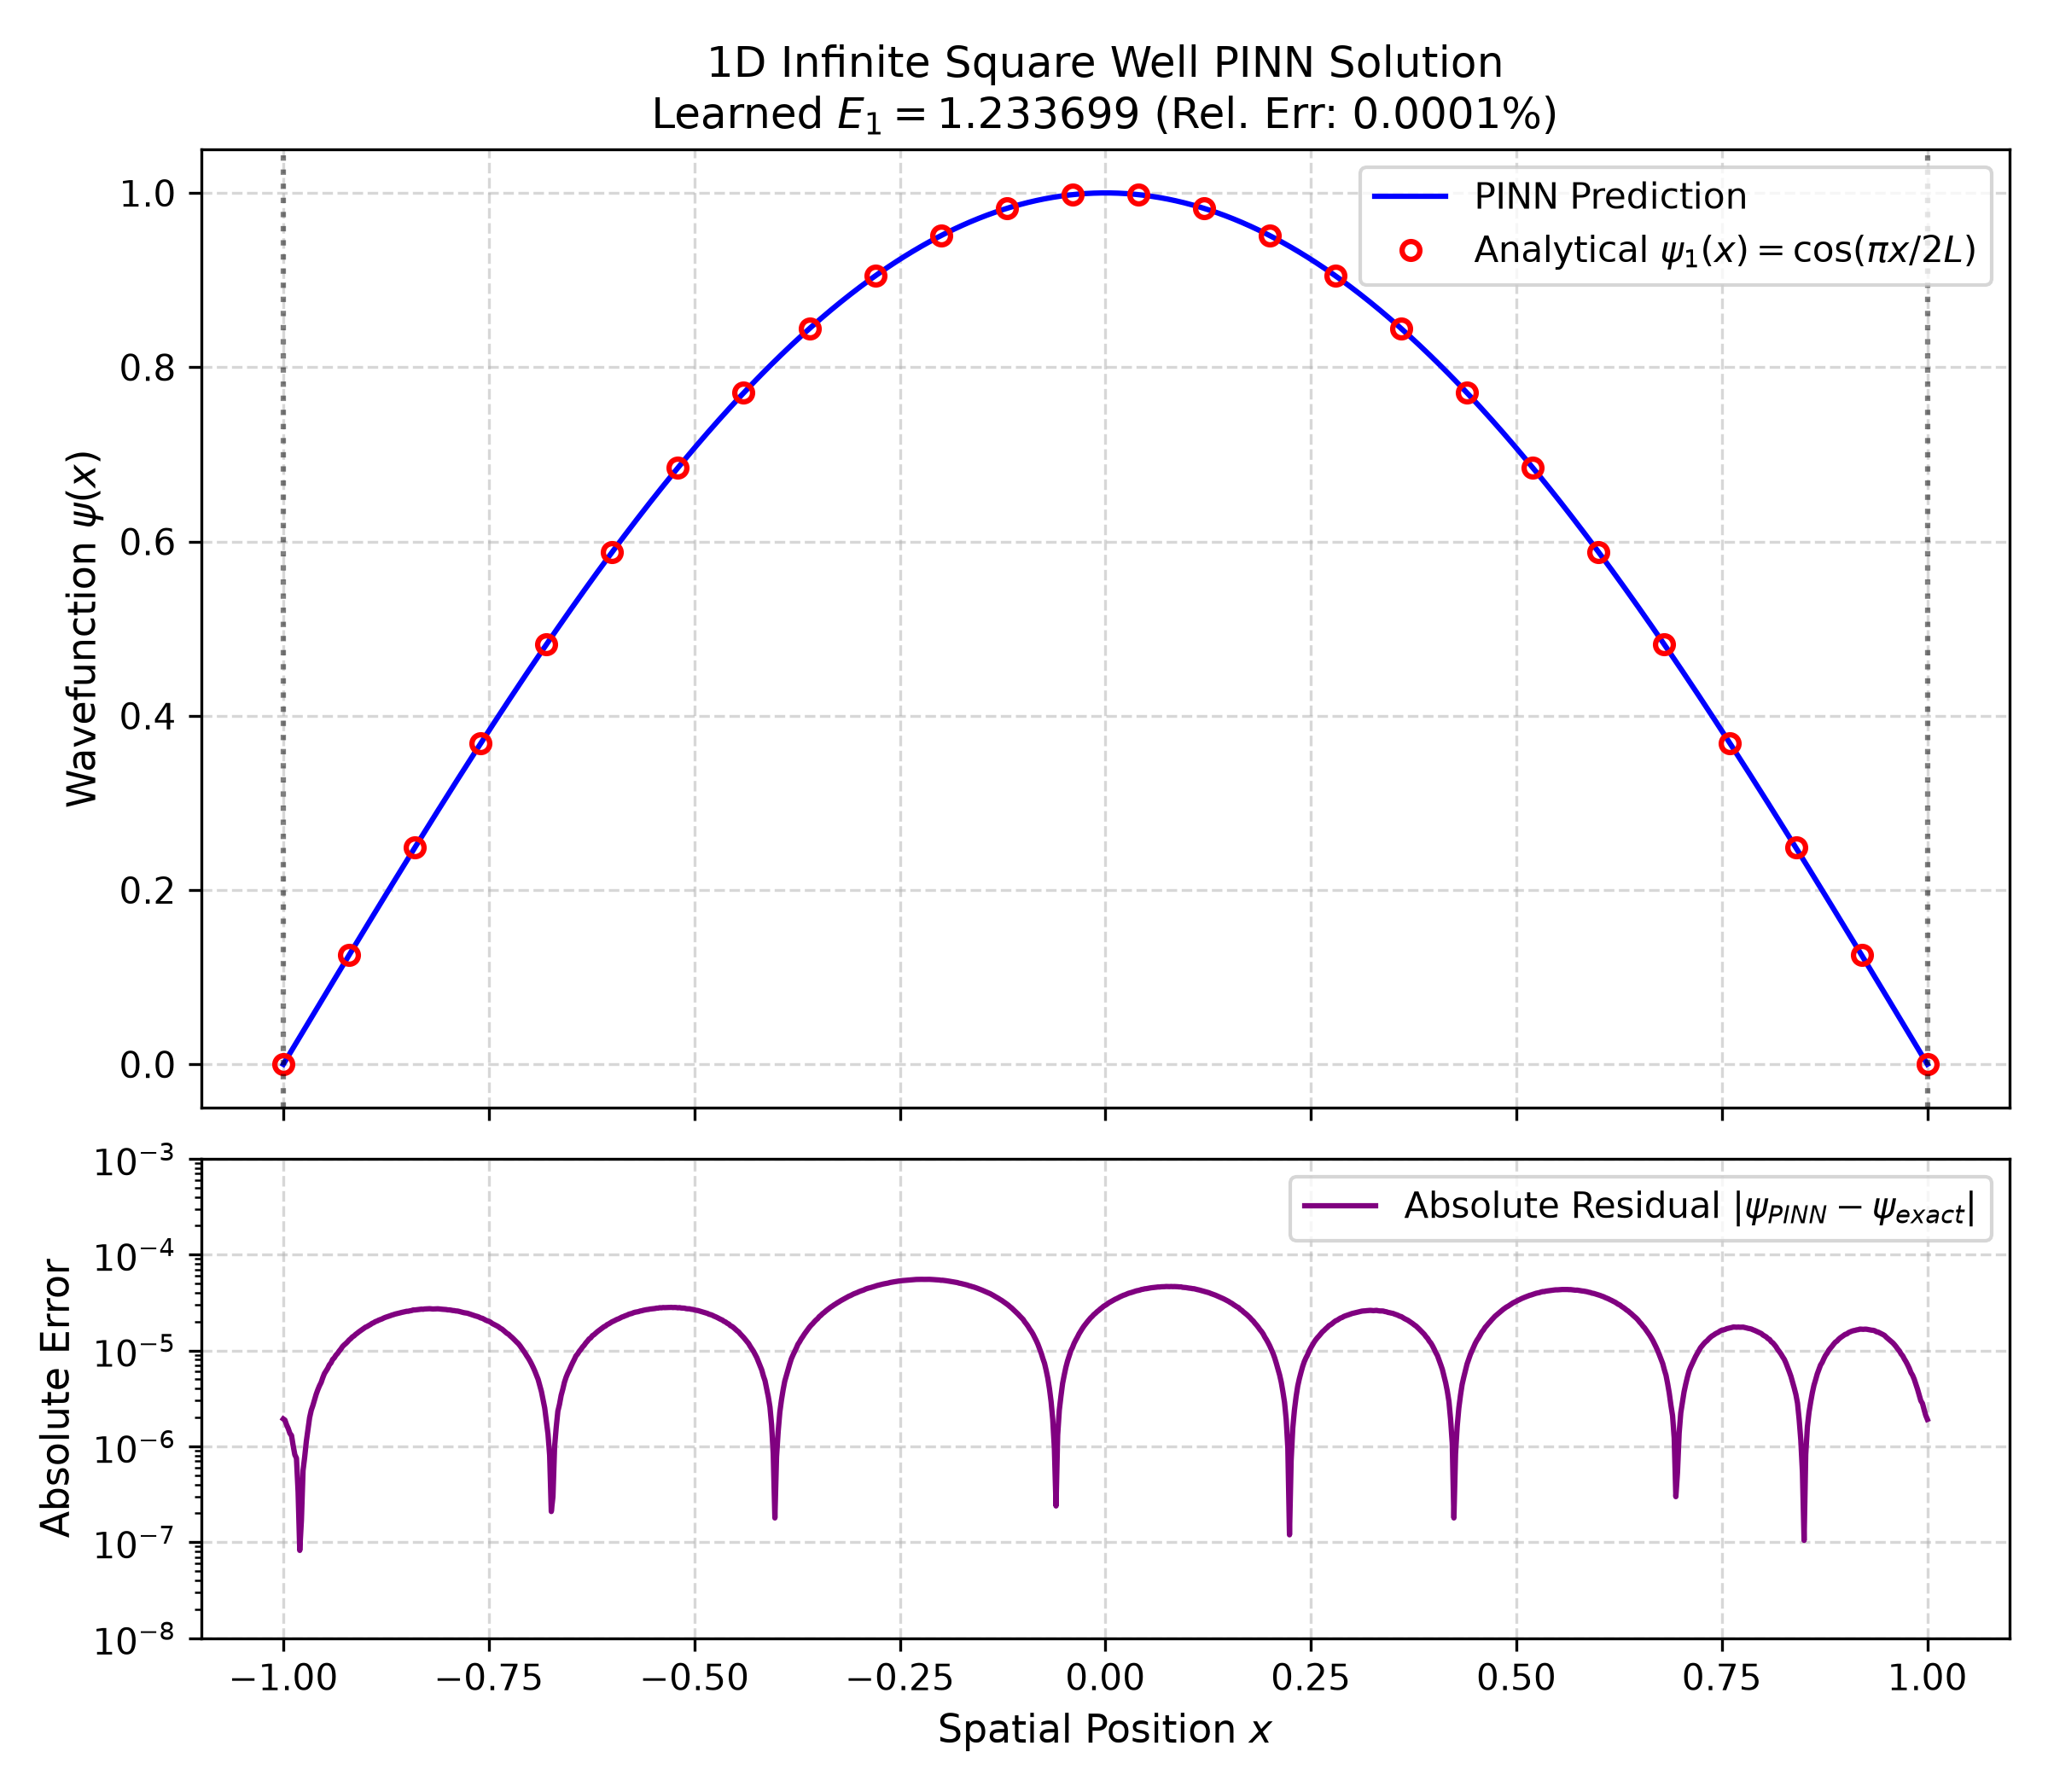
Physics-informed neural network · PyTorch · 4 hidden layers, width
50, 200 collocation points · staged Adam then L-BFGS
A PINN for the 1D time-independent Schrödinger equation, with one
structural choice that changes what the model is doing: the energy
is an nn.Parameter optimized alongside the network
weights, initialized at 1.0. The eigenvalue is an output of
training, not an input to it. On the infinite well the model
recovers E1 = π2/8 to an absolute error
of 2×10⁻⁶, in about 17 seconds on CPU.
Three residuals: the PDE itself, the vanishing boundary condition,
and a normalization term without which the trivial solution ψ
≡ 0 satisfies everything else. The constraint terms carry ten
times the weight of the PDE residual, because they're exact
conditions while the PDE is only sampled at collocation points.
Training runs in two phases, and the split earns its place. Adam
plateaus around 10-4 in the loss after 5,000 epochs,
ending at E = 1.232271. Five hundred L-BFGS steps with
strong-Wolfe line search take the loss two further orders of
magnitude to 1.9×10⁻⁶
and gain roughly two digits in the energy.
Fig. 2 Learned wavefunction against
the analytic ground state, and the energy converging across both
optimizer phases.
The method carries a real caveat: the PDE residual is minimized by
any eigenpair, and nothing in the loss prefers n = 1. Convergence
to the ground state here follows from initializing E below
π2/8. Initialize near 5.0 and it converges to E2
= π2/2 instead. The infinite well was chosen because
it has a closed form to check against, which makes this a test of
the method rather than a use of it.
Turns a master résumé and a job posting into a tailored LaTeX
draft and a per-requirement coverage report. Built as a RAG app,
shipped without it: chunking cut paragraphs from their role
headers, so true accomplishments landed under the wrong
employer. At ~3,000 tokens against a 65k window there was no
context limit to solve, so the full document now goes into the
prompt and the retrieval layer came out.
TinyShakespeare, decoder-only transformer, no high-level
abstractions, 4.82M parameters across 6 layers. Best remembered
for a measurement result rather than a modeling one: validating
once per epoch recorded the best loss 5,300 steps past where the
real minimum sat. Evaluating every 500 steps instead moved it
from 1.63 to 1.46 on identical architecture and data.
A markdown reference for terminal commands I use often enough to
need and rarely enough to forget: docker, git, LaTeX, python
environments, CUDA setup. Served by a local web app with search
and copy buttons. Python standard library only, no dependencies,
runs offline or in a container.
Research
2019-2020
ttHH production with boosted decision trees
Undergraduate thesis, Santa Cruz Institute for Particle
Physics. Signal-background separation for a rare final state,
raising expected significance 35% over the cut-based selection
(0.26σ to 0.35σ) with an AUC of 0.86.
Thesis (PDF) ·
Repository
2020-2021
ttHH production with deep neural networks
Continued as a staff researcher at SCIPP after graduating,
moving the same analysis from boosted decision trees to deep
neural networks in TensorFlow and Keras. Expected significance
improved 174% over the BDT result (0.35σ to 0.96σ), close to
four times the cut-based baseline.
Repository
2021-2023
CMS MIP Timing Detector
High Energy Physics Lab, University of Virginia. SiPM
characterization and readout with the FERS system; analysis
pipelines on the Rivanna HPC cluster.
2020
Aromatic copper hydride cages
First author · AAAFM Energy 2020;1(1):16–26
Synthesis and characterization of air-stable
Cu8HL′6PF6
clusters using a novel aromatic dibenzyl dithiocarbamate
ligand, candidate materials for reversible hydrogen storage.
Characterized by ESI-MS,
1H-NMR, powder XRD, FTIR, UV-Vis, and ICP. Work
done at Los Angeles City College before transferring to UC
Santa Cruz.
Zenodo ·
DOI
Toolkit
Machine learning
PyTorch
TensorFlow / Keras
scikit-learn
Transformers
PINNs
Linear probing
Boosted decision trees
Programming & tools
Python
C++
Git
Docker
Linux
HPC clusters
LaTeX
Bash
Data analysis
ROOT / uproot
Coffea · awkward-array
NumPy · pandas · SciPy
Monte Carlo simulation
Statistical inference
Matplotlib
Data pipelines
Experience
2024-Present
Technical Support / Operations Specialist
Los Angeles Public Library, contracted through Managed Career
Solutions.
2021-2023
Post-baccalaureate researcher
University of Virginia.
2020-2021
Machine Learning Researcher
Research at the Santa Cruz Institute for Particle Physics.
2017-2020
B.S. Physics
University of California, Santa Cruz.
Contact
I'm looking for research engineer and applied scientist roles, in LA
or remote. If you work on machine learning and want to reach out, my
email's open.